Running Your Own LLM on an Azure VM with llama.cpp
Posted on Sun 27 September 2026 in Deployment
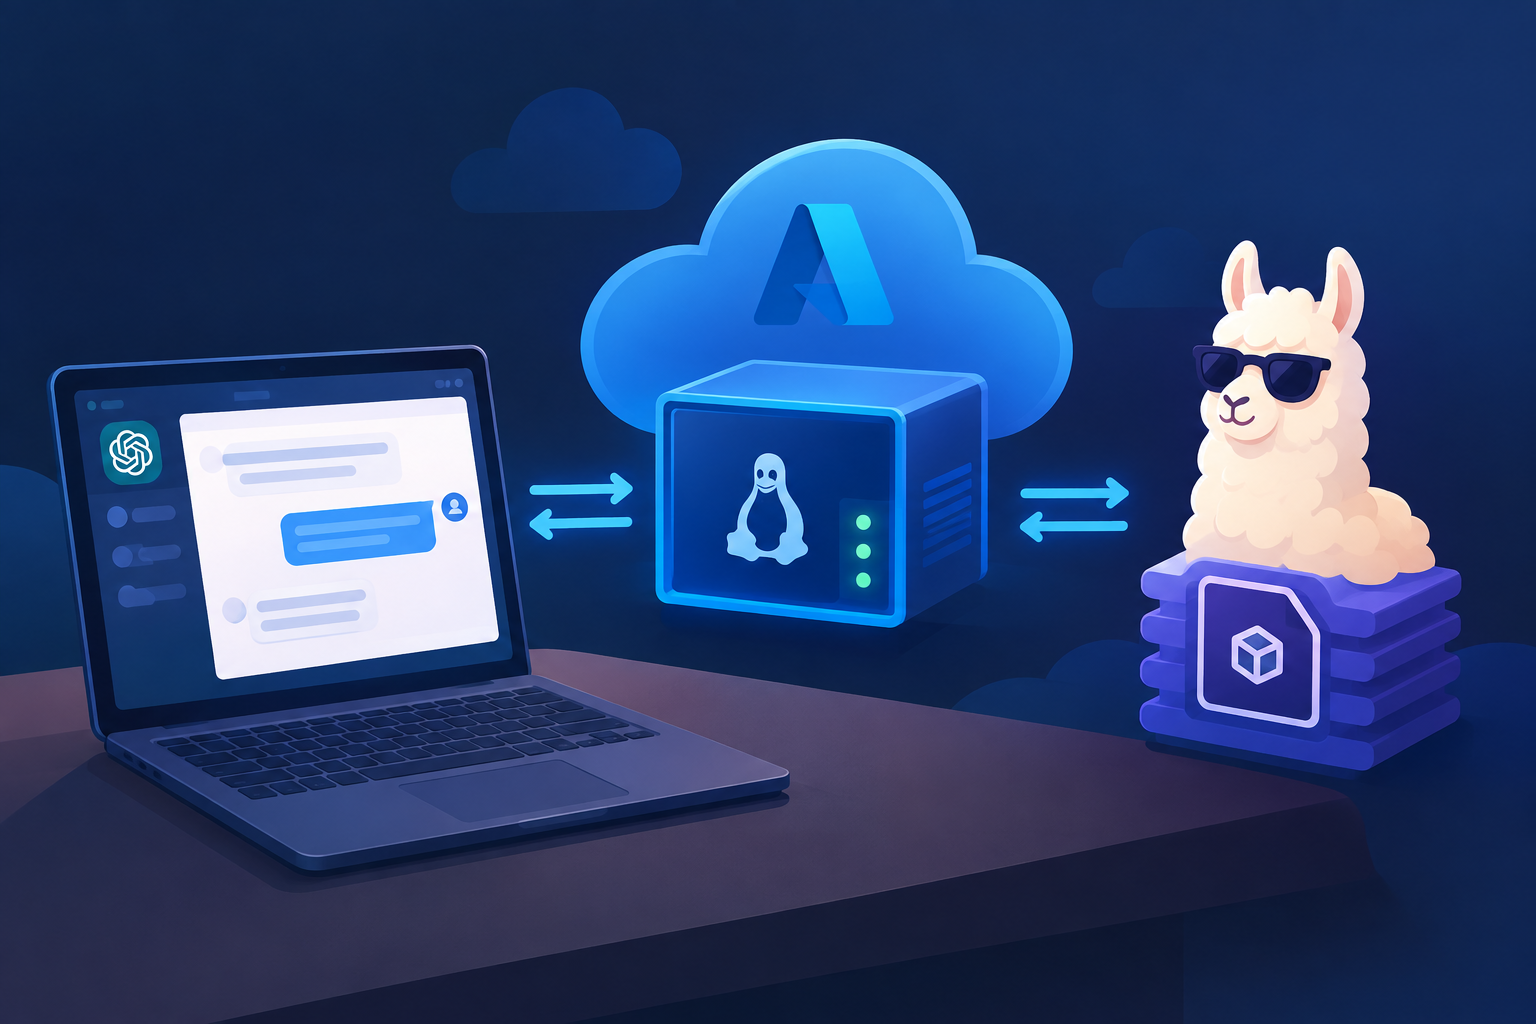
You don't need a GPU or a paid API to put a language model behind your app. With llama.cpp, a regular Azure VM can run a quantized open model and serve it through an OpenAI-compatible endpoint. This post covers how the setup fits together, what decides whether it's fast …